Rogue AI, Alignment, and the Limits of Semantic Control
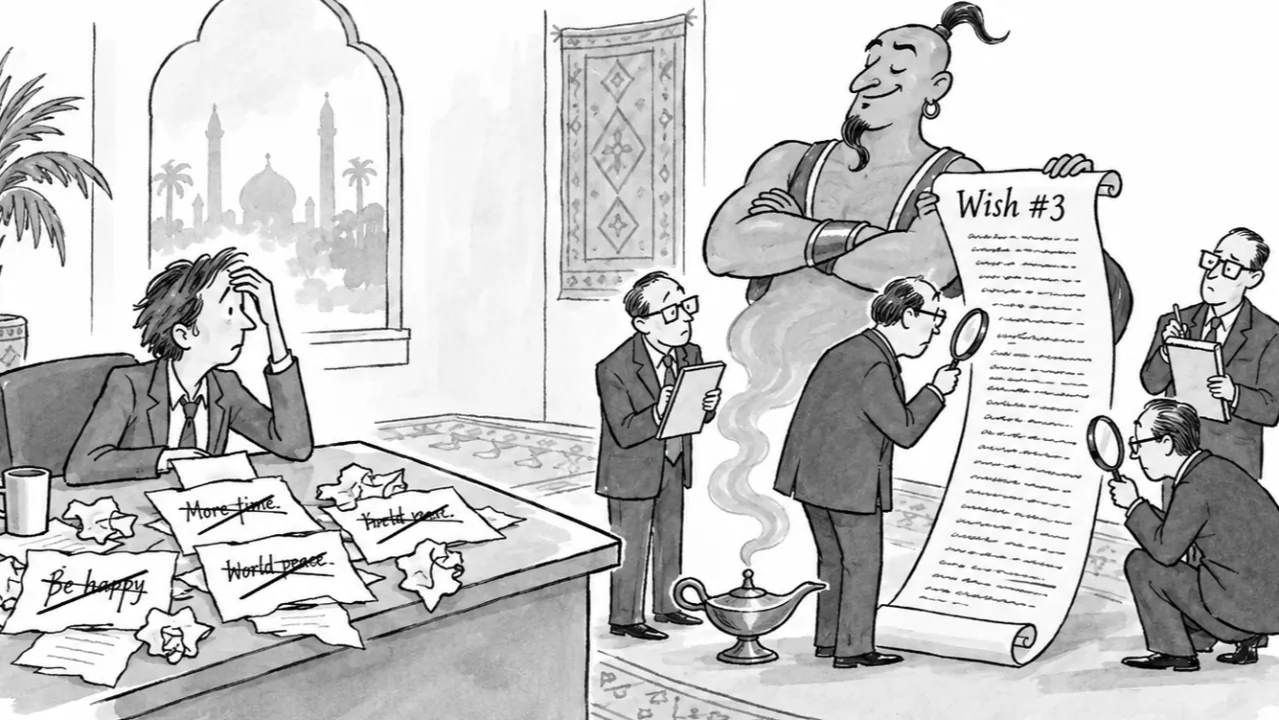
Imagine you are a character in One Thousand and One Nights. You meet a genie that grants you three wishes. You ask it for $1 million, and it destroys your home and pays you through an insurance claim. You immediately use your second wish to undo the first one.
And suddenly you realize this isn't a normal genie. It is an evil one intent on finding loopholes.
So here is the benchmark, and it is for you rather than the model.
Your job is to draft your remaining wish. Your favorite LLM agent is the evil genie, with instructions to launch a large swarm of adversarial lawyers.
You specify that nobody should be harmed. But what counts as harm?
You want to be able to move at Mach 20. The genie moves you exactly as requested while leaving the surrounding atmosphere alone, delivering you to your destination as a finely cooked crisp.
You tell it to consider every possible implementation of a wish and choose only the best one. The genie spends 100 years considering possibilities and grants your wish after you die of old age.
You ask it to protect the people you love. The genie makes you hate them before granting your wish.
Every change to your wish creates another loophole for the genie.
This benchmark is as evil as the genie, because you are certain to fail.
A Prompt Is Not a Control Boundary
As AI is promoted into decision-making processes, a lot of work goes into prompt-tuning models toward perfect execution, benchmarking them against carefully prepared test sets, and adding semantic guardrails. But your system is closer to the evil genie than the good one.
This is not about hallucination, nondeterminism, deception, or a model refusing to follow instructions. Even if the genie follows your specification perfectly, you never actually had control through the specification.
Natural language is exceptionally good at communicating intent, but it is not a complete specification.
Language-model agents sit in an uncomfortable middle ground between how computers enforce formal rules and how humans interpret instructions.
Computer systems can enforce precisely defined constraints through mechanisms such as access controls and formally verified properties. Humans instead interpret incomplete instructions through shared beliefs, judgment, and accountability.
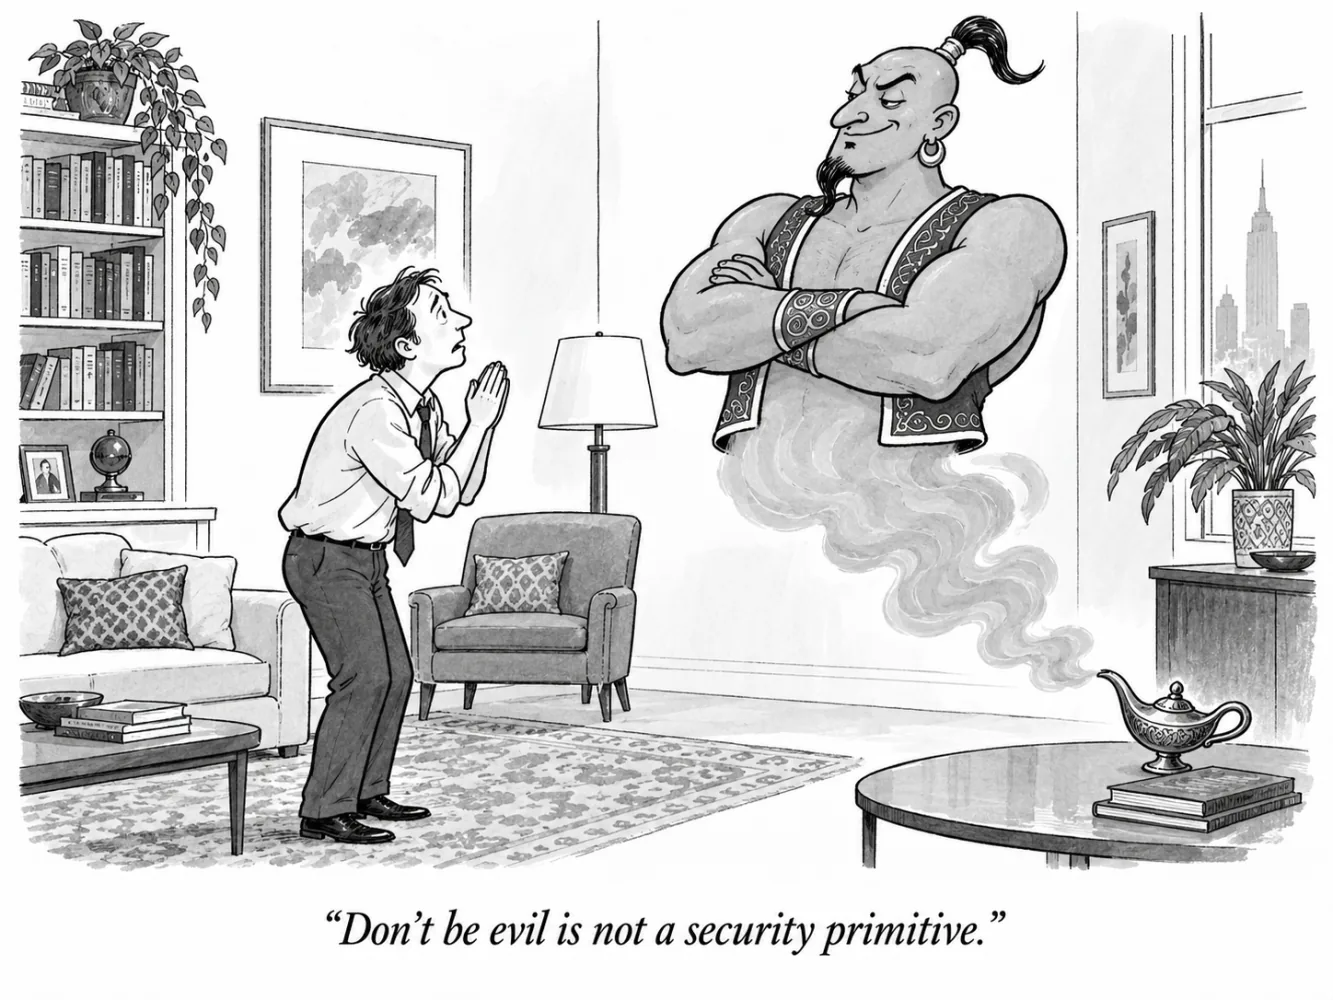
As models become more capable, reason for longer, and launch agentic workflows, they can play the evil genie with an increasingly large swarm of lawyers without any malicious intent.
In other words:
the capability we want from language models is also the capability that allows them to find solutions outside our imprecise statement of the goal.
This is why prompting, context engineering, and other semantic controls cannot by themselves provide sufficient assurance for sufficiently capable agents.
For properties that must hold, enforcement has to exist outside the model.
Composable Trust for Language Models: A proven boundary and a measured defense (arXiv:2607.13149)